SERVICE · REMOTE FROM MEXICO
Web scraping services and public data extraction
A lot of decision-useful information — competitor prices, catalogs, listings, publications — lives on the web, scattered and in no format you can analyze. I build Python extractors that collect it on a schedule, clean it and deliver it ready to use in Excel, CSV, a database or a dashboard.
This is a fit if…
- You manually check competitor sites to compare prices or products.
- You need a dataset of public listings to analyze a market.
- You want a recurring report with information you currently copy from several pages.
- Your research process depends on checking the same sites every day.
What you get
- Feasibility review: sources, terms of use, frequency and volume.
- Python extractor with error handling, retries and rate limits.
- Data cleaning and normalization: prices, dates, categories and duplicates.
- Delivery to Excel, CSV, Google Sheets, a database or an API.
- Scheduled runs and alerts when a source changes its structure.
How I work
- 01
Feasibility
I review each source: whether the data is public, what its terms and robots.txt allow, and whether an official API would be a better route.
- 02
Prototype
I extract a sample so you can confirm the fields and format work for your analysis.
- 03
Production
I build the full extractor with cleaning, error control and the agreed schedule.
- 04
Maintenance
Sites change; the system alerts you when a source stops responding the same way so it can be adjusted.
What I need from you
- The list of sites or sources and the fields you need.
- What you will use the data for, to choose format and frequency.
- The destination: spreadsheet, database or your own system.
Good to know
- I only extract public information and respect each site's terms; I do not collect personal data or bypass logins or protections.
- If a site changes its structure, the extractor needs adjustments.
- Some sources block automated extraction; in that case I propose alternatives such as official APIs.
Problems I solve with this service
Competitor price monitoring
Collect competitors' public prices on a schedule and get changes in a clear report.
Read solution →Real estate listings data for market analysis
Gather public property listings into a clean database to analyze prices by neighborhood.
Read solution →Agricultural price tracking from public sources
Bring terminal-market and official price reports into one dashboard to decide when and where to sell.
Read solution →Related work
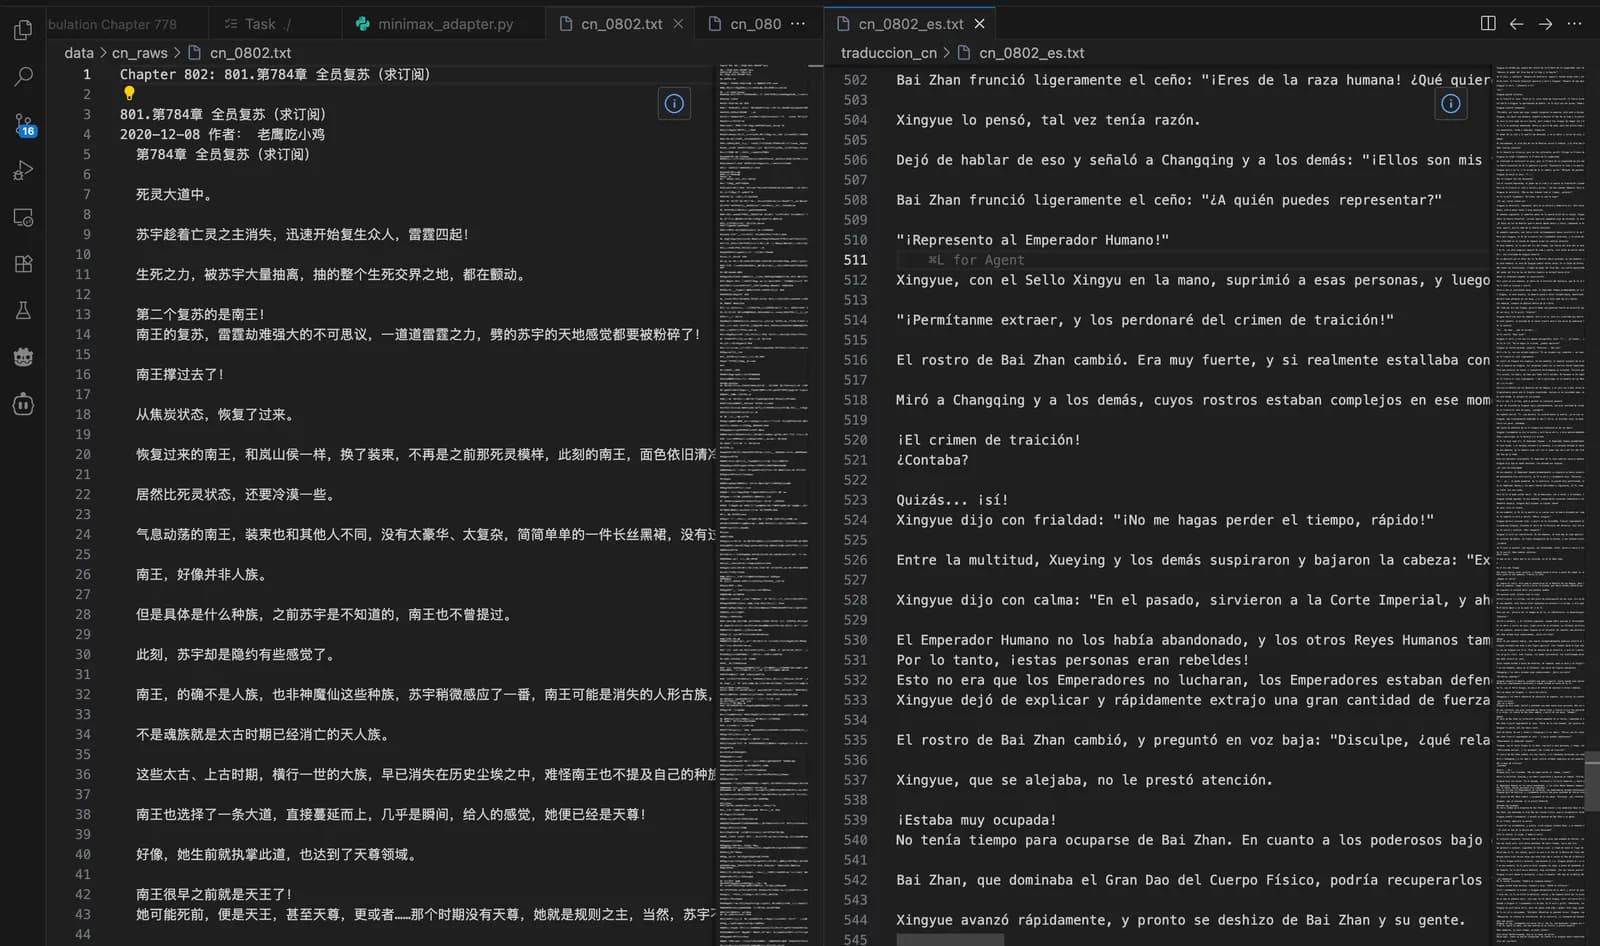
NLP Pipeline
Multi-model extraction and translation of web content, with batch processing and consistency checks.
View case study →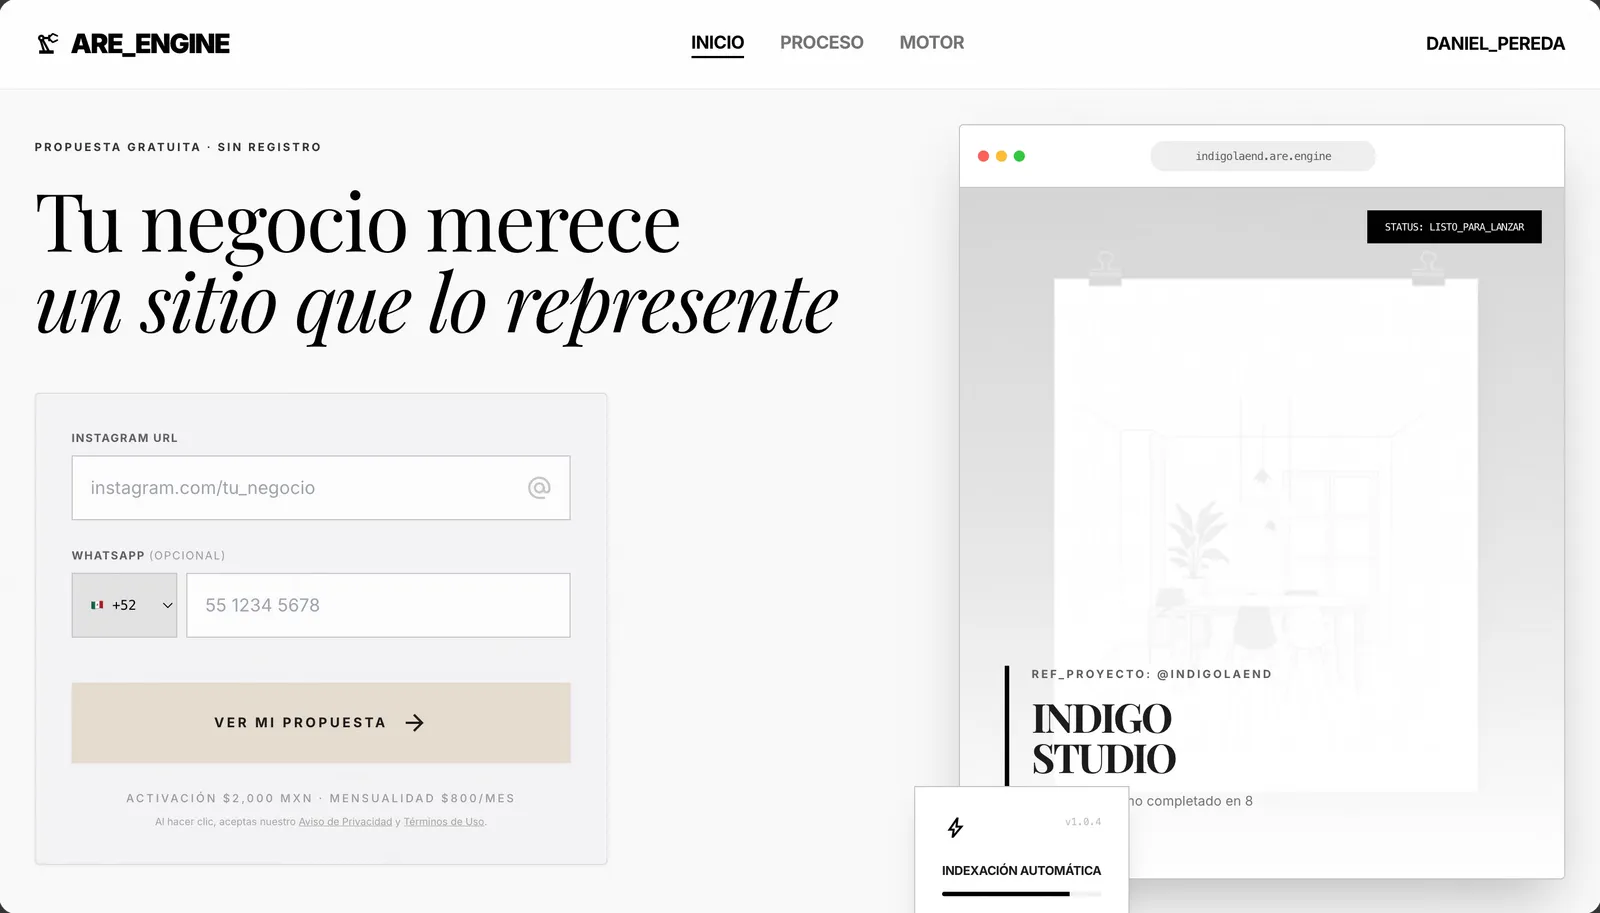
ARE Engine
An engine connecting brand analysis, content generation and website creation for local businesses.
View case study →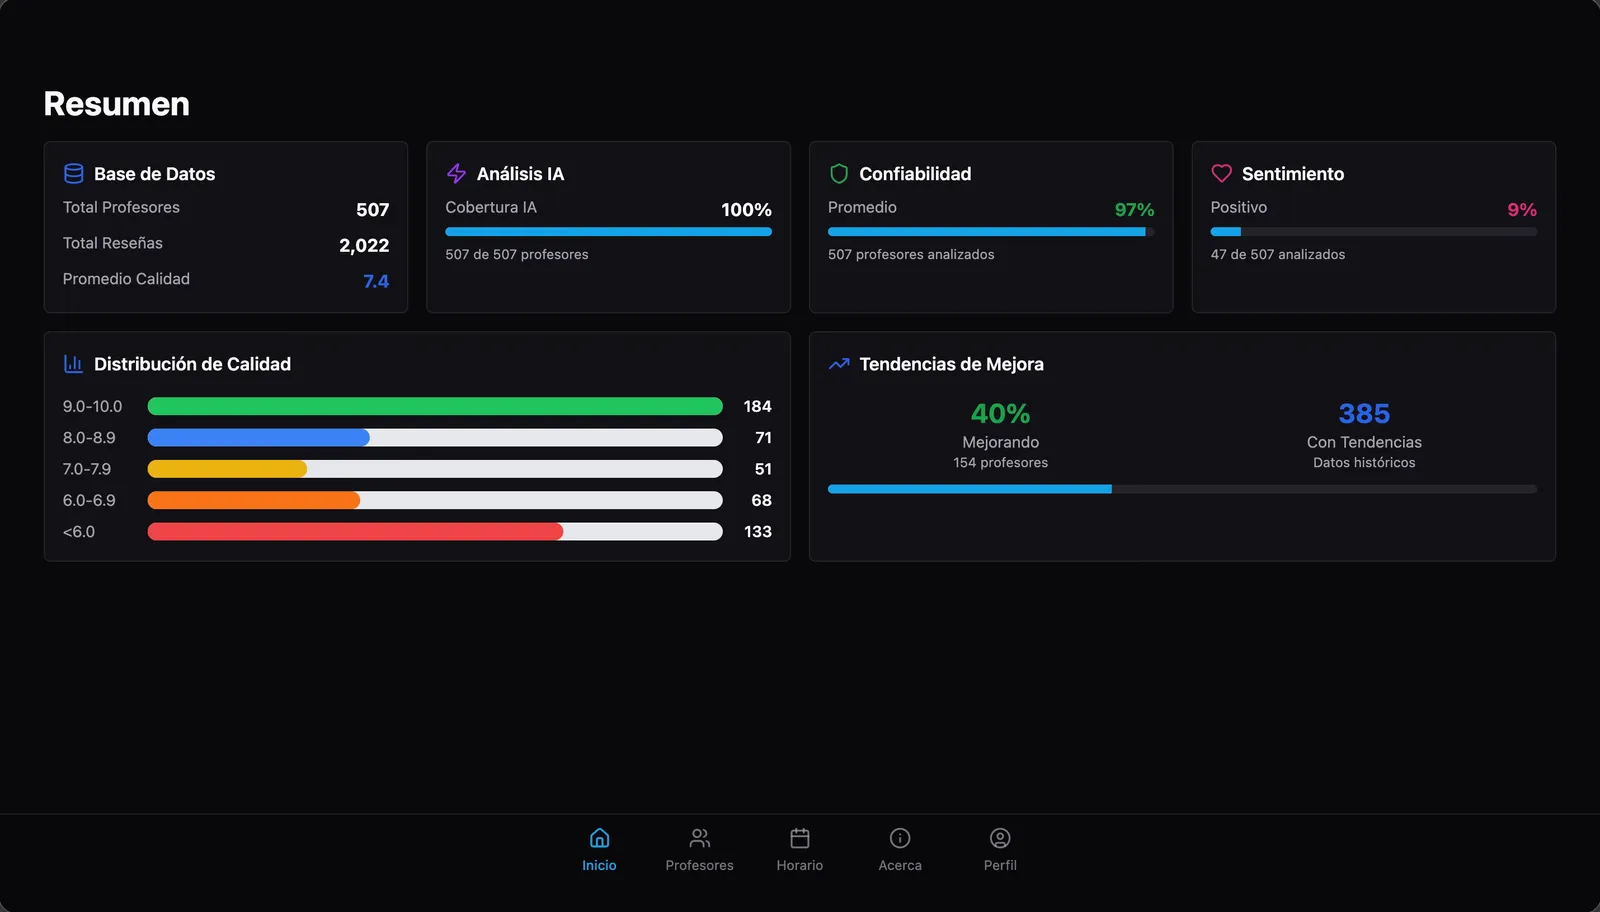
EvaluaProf
Ingestion, normalization and analysis of academic evaluations to turn responses into useful information.
View case study →Make a better-informed decision
Frequently asked questions
Is web scraping legal?
Extracting public, non-personal information is generally acceptable, but it depends on each site's terms and on how the data is used, and rules differ by country. I review every source before starting and drop the ones that forbid it. This is not legal advice.
How often is the data updated?
As often as your analysis needs: once, daily, weekly or near real time. Higher frequency means more load on the sources and more infrastructure.
What format will I receive?
Whatever you use: Excel, CSV, Google Sheets, a PostgreSQL database or a filterable dashboard.
How much does a scraping project cost?
It depends on the number of sources, their technical complexity (dynamic pages, pagination, blocking) and frequency. A one-off extraction is simpler than continuous monitoring.
Want to talk it through?
Tell me what you need to solve. I’ll reply with specific questions, a possible scope and a clear next step — no commitment.