NLP / DATA ENGINEERING · December 2025 – January 2026
NLP PipelineFrom noise to meaning.
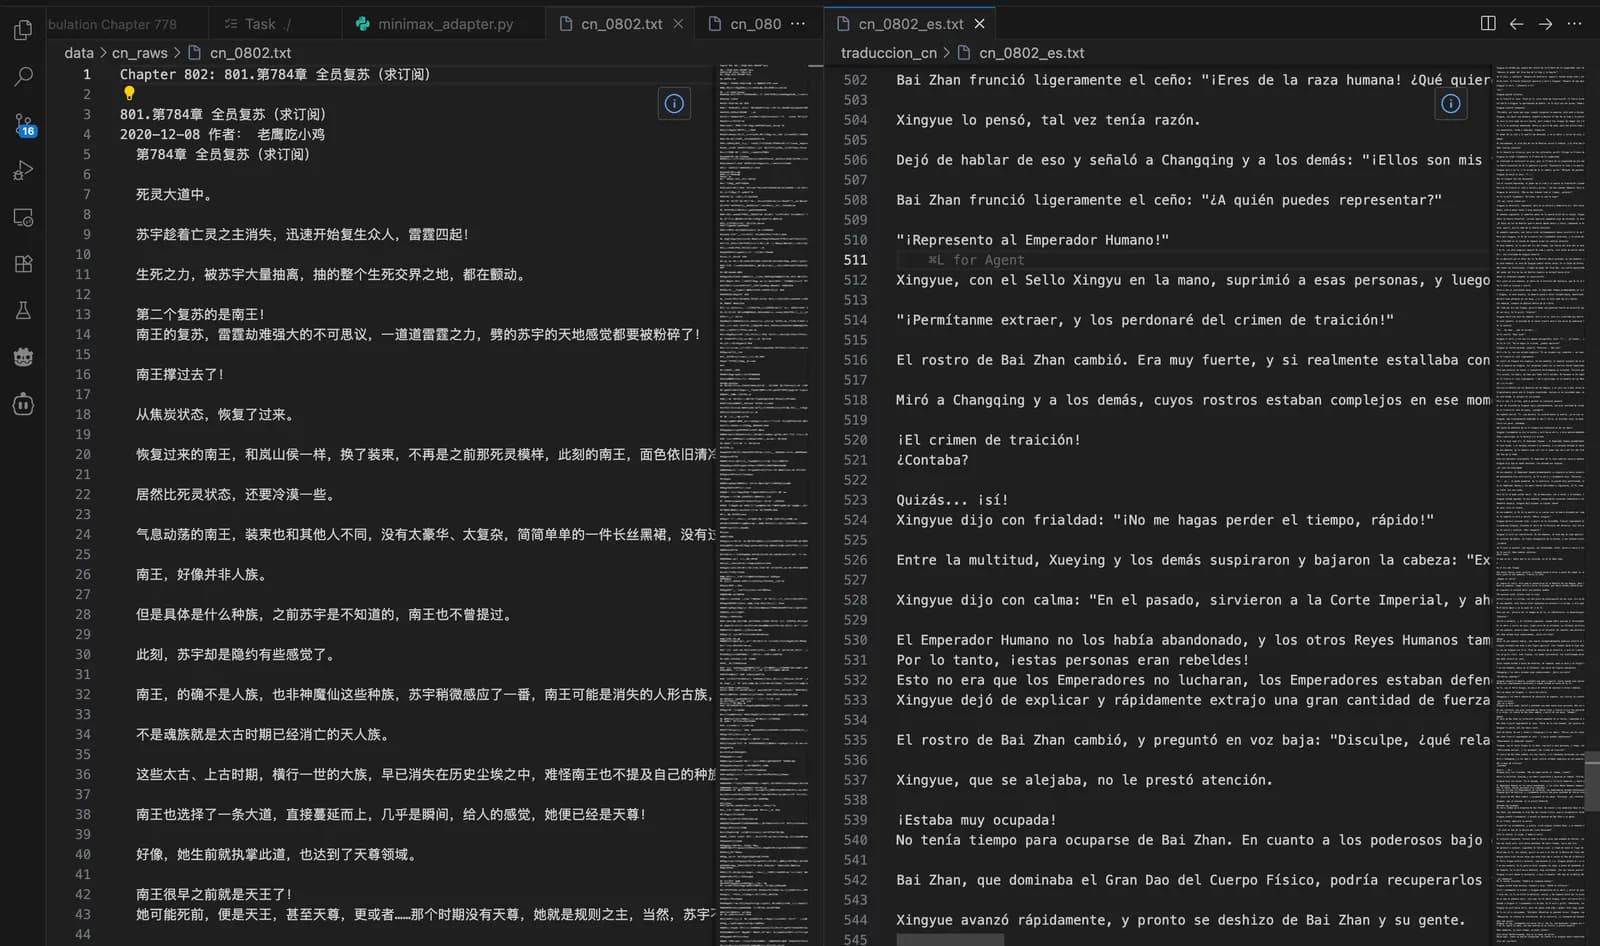
Multi-model extraction and translation of web content, with batch processing and consistency checks.
VERIFIABLE EVIDENCE · OCTOBER 2026
- Source code
- GitHub · Python ↗
The problem
Manually extracting, organizing and translating web content introduces inconsistencies and repetitive work.
My contribution
Construction of the end-to-end pipeline and model adapters, with text normalization and post-processing.
How it works
- Web content
- Extraction
- Translation
- Structured text
Personal project
A pipeline that extracts, normalizes, translates and formats multilingual text through batch processing and LLM orchestration.
The interactive demo walks through a prepared sentence; it does not query external sites or run a live translation.
Design decisions
- Normalize content before processing it with different models.
- Keep long-form content consistent and separate the processing stages.
I can build something like this for you
Process automation and integrations
Connect your tools and remove repetitive work: automated reports, data entry and alerts.
View service →AI chatbots and applied AI
AI assistants and workflows that answer, classify and extract data, with human review.
View service →Web scraping and data extraction
Collect public web data in an orderly way: prices, catalogs and listings.
View service →Facing a similar problem?
We can talk through how you work today, define the scope and find a starting point.
Tell me your idea ↗